Sandbox lifecycle
MicroVM sandboxes are stateful. A running VM suspends itself when idle and wakes on the next request; you can also pause it (snapshot, quota slot freed), resume it under the same vm_id, or fork it into independent copies. Command output streams over SSE as it is produced.
States
Swipe sideways to pan. Tap a state or an arrow.
1. POST /v1/runtime/schedule
AgentSpec: image, isolation, limits, egress, secrets, and optional idleTimeoutSecs.
server/main.go:787handlers/runtime.go:1730handlers/runtime.go:754
Idle suspend
Set idleTimeoutSecs on the schedule request (--idle-timeout N on the CLI; 0 or unset = never). When a sandbox sees no exec, tool call or file request for that long, it is snapshotted and its compute and quota slot released; the scheduler sweeps every 10 s on activity reported with the 30 s node heartbeat, so suspension can trail the timeout by up to ~40 s. The next exec or file request (REST, CLI or SDK) resumes it transparently: the caller sees a slower first response (~4 s for the in-guest exec channel to re-establish), not an error. A VM paused by an operator (POST /pause) is never auto-resumed. The snapshot stays in storage while suspended. Lifecycle latency numbers (Lima nested-virt, Apple M4 Max, aarch64 — indicative, not bare metal): docs/benchmarks/runtime-latency.md.
LANTERN_MAX_FORK_COUNT (ceiling 1000).Snapshots
A snapshot captures the VM's guest memory, its vmstate and its writable disk. The disk is copied while the VM is paused for the memory snapshot, so memory and disk describe the same instant (a restored guest's page cache matches the disk underneath it). Every snapshot is stored as three artifacts:
snapshot— Firecracker vmstatemem— guest memory (as large as the VM's RAM)rootfs— the captured disk
Restore and fork stage from the captured disk. Resume, idle wake and each fork copy the snapshot's rootfs to a per-VM writable path (or into the jail), so files written before the snapshot are still there and writes after it stay private to that VM. A legacy snapshot taken before disks were captured has no rootfs; it restores onto the base image, which does not match its memory, so re-snapshot long-lived VMs.
Where snapshots are stored
The runtime-manager's snapshot store keeps the canonical copy on local disk and optionally mirrors it to S3/MinIO. All reads go through the local tier and fall back to S3 when the local copy is gone.
| Env var (runtime-manager) | Default | Purpose |
|---|---|---|
SNAPSHOT_DIR | /var/lib/lantern/snapshots | Local tier root, laid out <agent_version_id>/<vm_id>/<snapshot_id>/ |
S3_ENDPOINT + S3_BUCKET | unset (S3 tier off) | Enable the S3/MinIO mirror under snapshots/<agent_version_id>/<vm_id>/<snapshot_id>/ |
AWS_ACCESS_KEY_ID / AWS_SECRET_ACCESS_KEY | unset | S3 credentials (same variables the control-plane uses) |
An S3 upload failure is logged and does not fail the snapshot; the local copy is already safe. Retention is applied after every write: the newest 3 snapshots per VM are kept and anything older than 7 days is deleted.
Cost
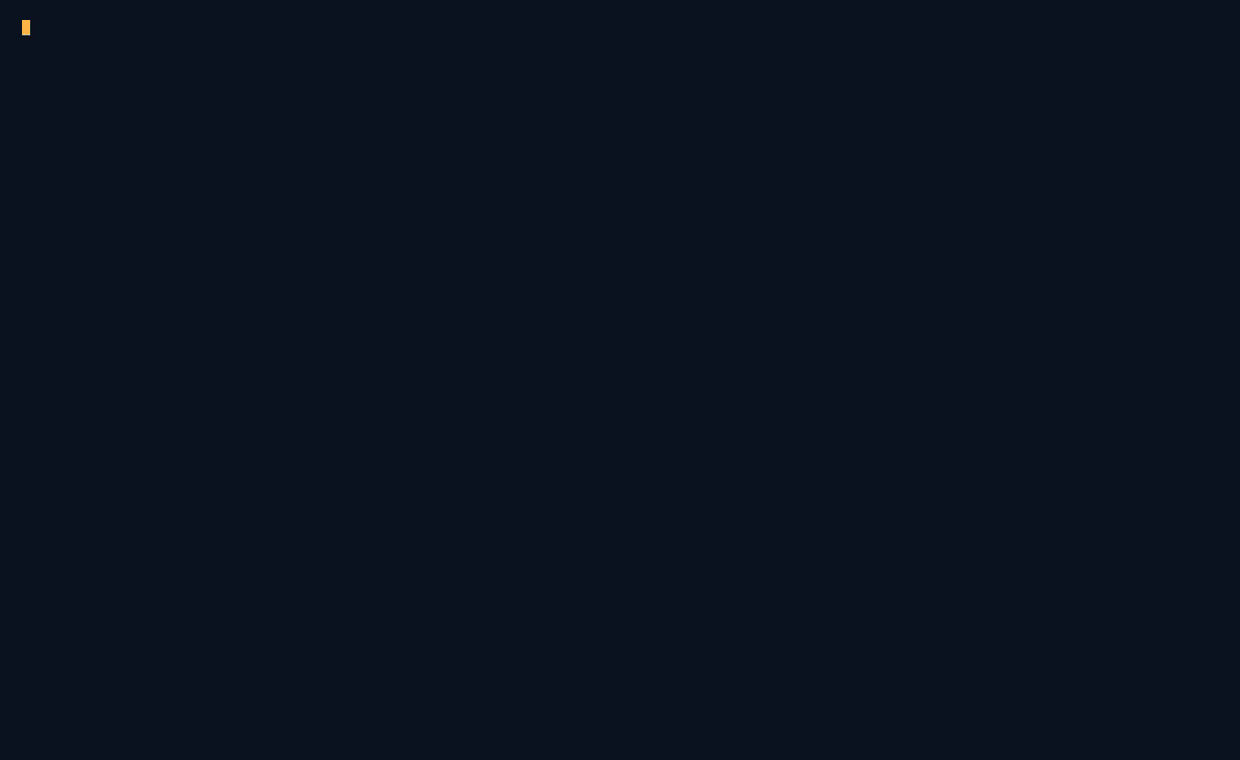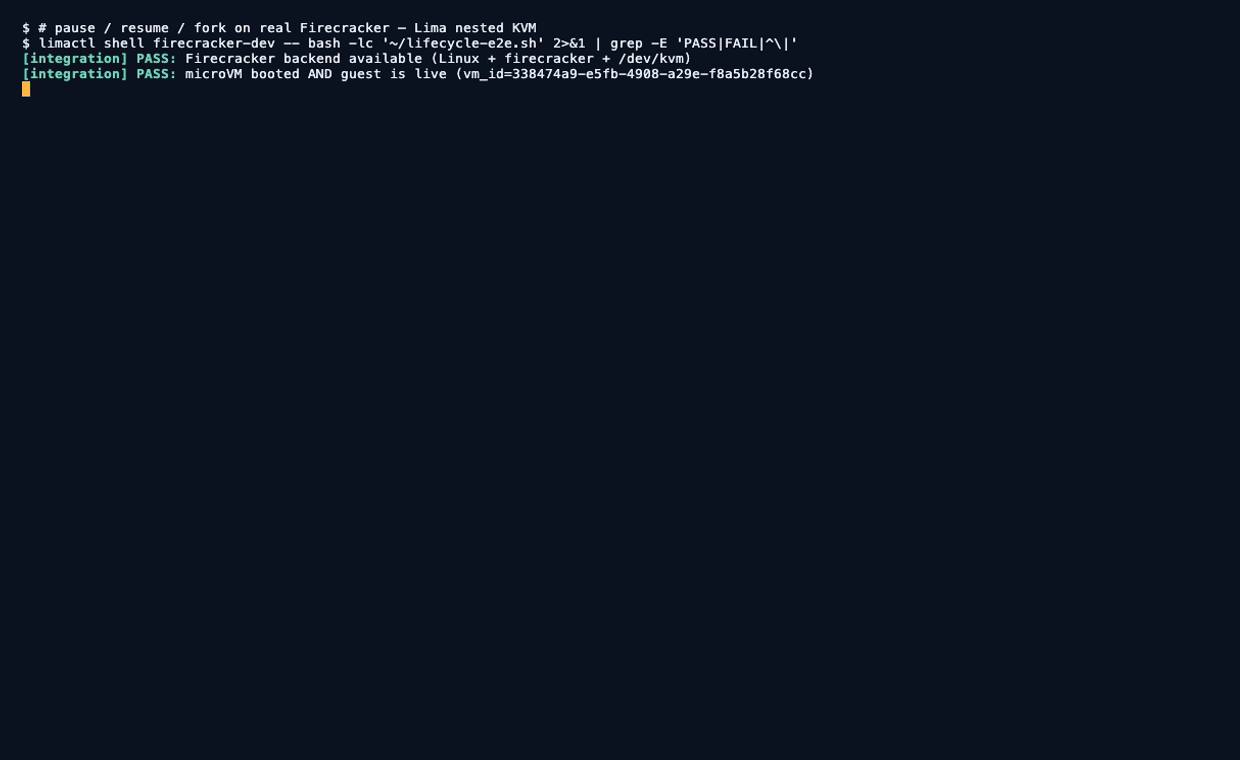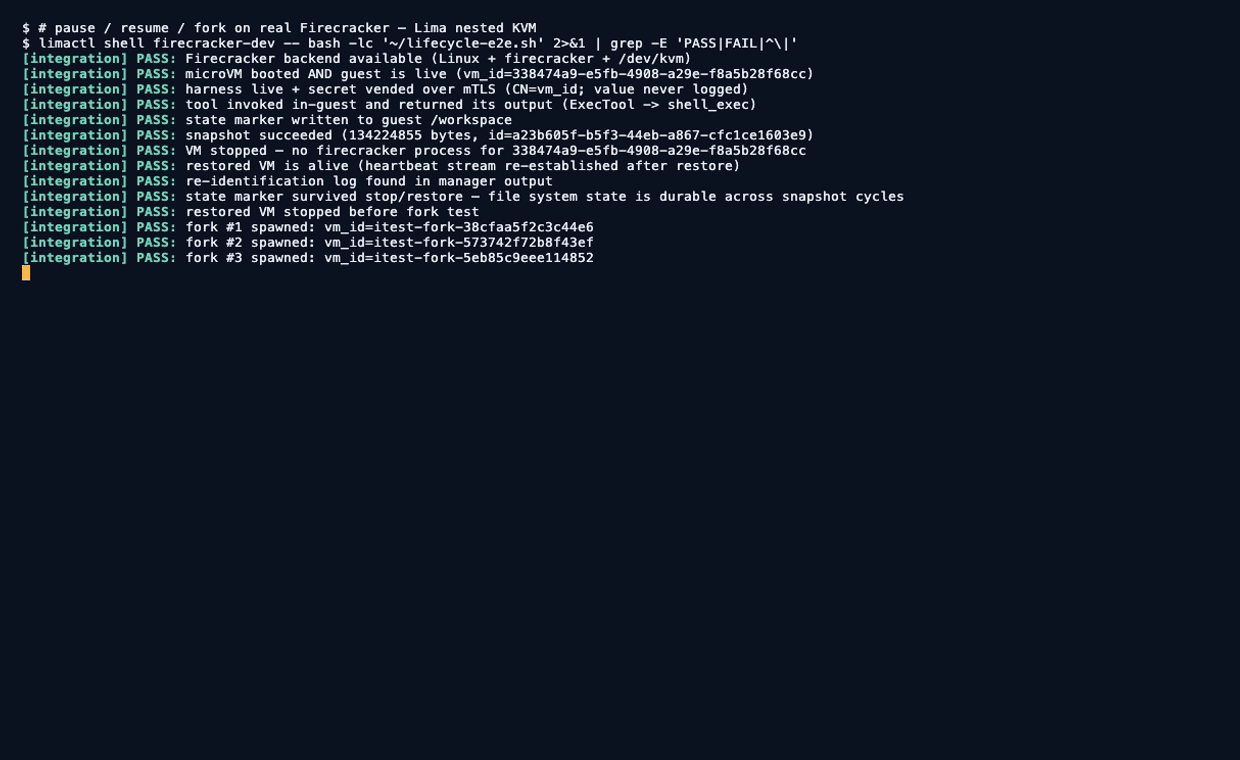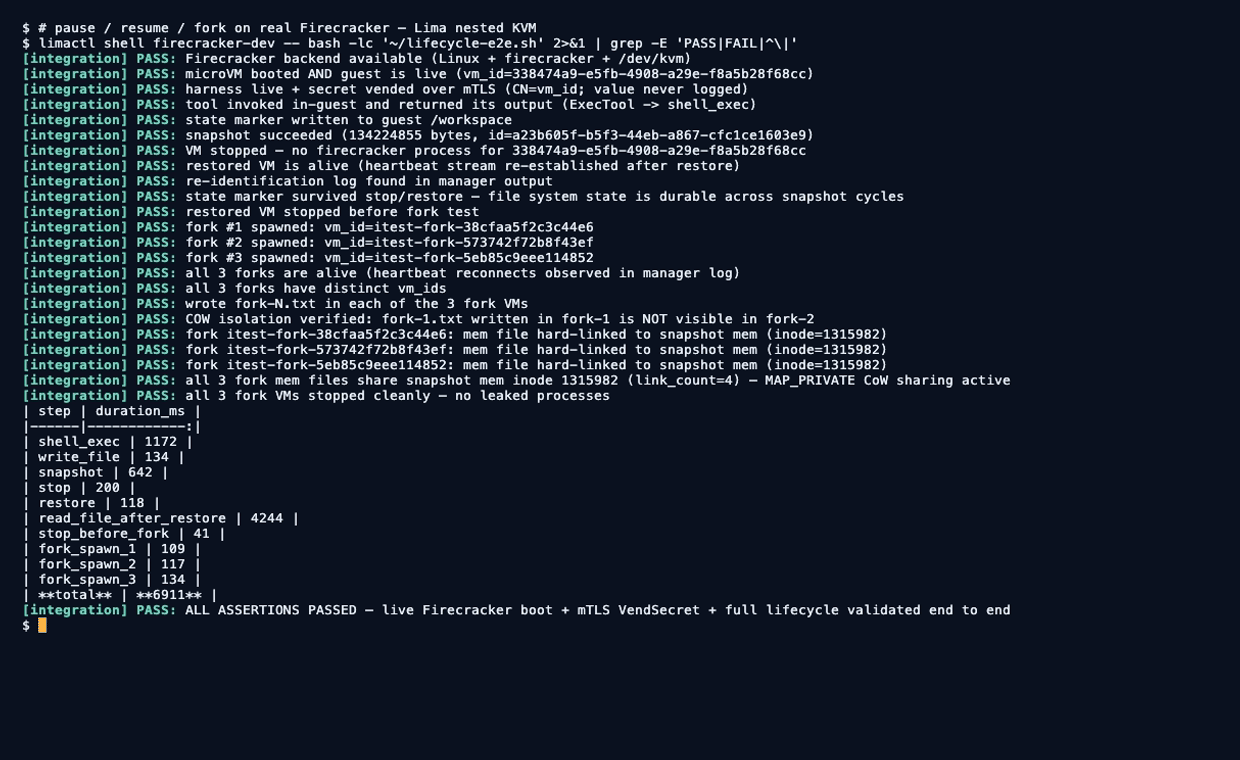
Each snapshot stores mem (up to the VM's RAM) plus a full copy of the disk, and every restore or fork copies the disk again. Disk capture happens while the VM is paused, so it adds to pause time (the copy reflinks on XFS/btrfs and byte-copies elsewhere). On the jailed path forks share the memory file via a hard link, so only the disk is copied per fork. Indicative numbers from docs/benchmarks/runtime-latency.md, measured in a Lima nested-virt guest on an Apple M4 Max (aarch64, 1 vCPU, 128 MiB VM, jailed). They are not bare-metal numbers:
| Step | Indicative |
|---|---|
| Memory snapshot (128 MiB, 134 MB written; measured before disk capture) | 634 ms |
| Restore (Spawn RPC) | 138 ms |
| Fork spawn (hard-linked memory + per-VM rootfs copy) | 131–160 ms |
| First exec after restore (p50 of 5 runs) | 2,857 ms |
The snapshot row predates disk capture, so add the rootfs copy (reflinked on XFS/btrfs, a full copy elsewhere) to snapshot time. The doc estimates the per-VM rootfs copy at ~5–50 ms for a 20–100 MiB image. After a restore the runtime-manager holds the first exec until the restored harness has re-identified and sent its first heartbeat (LANTERN_HARNESS_READY_TIMEOUT_MS, default 5 s), so a caller makes one call instead of retrying. On Lima that first exec lands in 2.6–3.1 s, almost all of it slow CPU-bound guest work under nested virtualization; bare-metal KVM has not been measured.
REST
# Pause: snapshot + stop. Frees the quota slot.
POST /v1/runtime/vms/{id}/pause
→ { "vmId": "...", "snapshotId": "...", "state": "paused" }

# Resume: same vm id. 402 if quota is exhausted, 409 if the VM is not paused.
POST /v1/runtime/vms/{id}/resume
→ { "vmId": "...", "snapshotId": "...", "state": "running" }

# Fork: count 1..100 by default (LANTERN_MAX_FORK_COUNT, ceiling 1000); forks share the snapshot memory copy-on-write. Each fork gets its own vm_id, cert and agent identity.
POST /v1/runtime/vms/{id}/fork
{ "count": 3 }
→ { "sourceVmId": "...", "snapshotId": "...",
    "forks": [ { "vmId": "...", "state": "running" },
               { "vmId": "...", "state": "failed", "error": "..." } ] }
GET /v1/runtime/vms/{id} additionally returns snapshotId and parentVmId (set on forks), and state may be paused. Restoring a snapshot onto a fresh TAP (resume, idle wake, fork; not broker mode) uses snapshot-load network_overrides, which needs Firecracker ≥ 1.12 with the jailer (tested on 1.15). Snapshots are owned by the tenant that created them; restoring another tenant's snapshot returns NOT_FOUND (ADR 0025). A restored VM re-identifies with a fresh identity rather than reusing the source VM's.
Streaming exec
POST /v1/runtime/vms/{id}/exec buffers output by default. Send Accept: text/event-stream to receive stdout, stderr, then exit events (or error) as they happen. Exec is execve-style: command is the executable, argv its arguments — pass /bin/sh with ["-c", …] for a shell line.
Files
Read and write files under the VM's /workspace. These run through the in-guest harness tool runner, so paths are confined to /workspace (escapes return 400) and files are accessed as the workload user. Content is UTF-8 text, at most 1 MiB (writes above return 413; larger reads are cut and flagged with X-Lantern-Truncated: true). Firecracker VMs only; other backends return 503.
GET /v1/runtime/vms/{id}/files?path=src          # → { path, entries: [{name, type, size}], truncated }
GET /v1/runtime/vms/{id}/files/content?path=a.txt  # → raw text
PUT /v1/runtime/vms/{id}/files/content?path=a.txt  # body = file bytes → { path, bytesWritten }
SDKs
TypeScript
const { snapshotId } = await client.runtime.pause(vmId);
await client.runtime.resume(vmId);                       // same vm id

const { forks } = await client.runtime.fork(vmId, { count: 3 });
for (const f of forks) if (f.error) console.warn(f.vmId, f.error);

await client.runtime.writeFile(vmId, "job.py", "print('hi')");
const { content } = await client.runtime.readFile(vmId, "job.py");
const { entries } = await client.runtime.listFiles(vmId);

for await (const ev of client.runtime.execStream(vmId, {
  command: "/bin/sh",
  argv: ["-c", "pip install -q requests && python job.py"],
})) {
  if (ev.type === "exit") console.log("exit", ev.exitCode);
  else process.stdout.write(ev.data);                    // stdout | stderr
}
Python
await client.runtime.pause(vm_id)
await client.runtime.resume(vm_id)

result = await client.runtime.fork(vm_id, count=3)
for f in result.forks:
    if f.error:
        print(f.vm_id, f.error)

await client.runtime.write_file(vm_id, "job.py", "print('hi')")
text = (await client.runtime.read_file(vm_id, "job.py"))["content"]
listing = await client.runtime.list_files(vm_id)

async for ev in client.runtime.exec_stream(vm_id, "/bin/sh", ["-c", "python job.py"]):
    if ev.type == "exit":
        print("exit", ev.exit_code)
    else:
        print(ev.data, end="")
CLI and Go
The Go SDK exposes PauseVM, ResumeVM, ForkVM, ListFiles, ReadFile and WriteFile.
lantern vm pause <id>
lantern vm resume <id>
lantern vm fork <id> --count 3
lantern vm ls <id> [path]
lantern vm cat <id> <path>
lantern vm put <id> <local-file|-> <path>
The dashboard VM detail page (/runtime/{vm}) has Pause, Resume and Fork actions.
Related: Isolation tiers, Durable execution, CLI reference.