Budgets
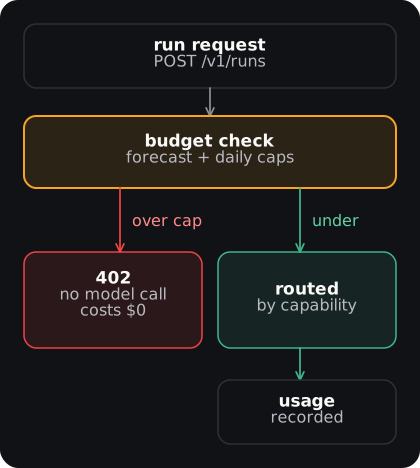
Per-agent spend and rate limits, set as policy. With hardFail: true, a call that would start while a limit is already reached is refused before the model is called: HTTP 402 on the REST paths, a failed step inside workflows. With false, the breach is logged and the call proceeds. If the budget cannot be read, hard-fail budgets fail closed.
A buggy loop can burn a month of model spend in an afternoon. Set a cap per agent: dollars per day, runs per day, tokens per day. With hard-fail on, the next call is refused before it reaches a model, not flagged afterward.
Setting a budget
Section titled “Setting a budget”PUT /v1/agents/{name}/budgetContent-Type: application/json
{ "maxCostUsdPerDay": 5.00, "maxCostUsdPerRun": 1.00, "maxTokensPerDay": 500000, "maxRunsPerDay": 100, "toolLimits": { "web_search": 50, "slack.post_message": 100 }, "hardFail": true, "notifyAtPct": 80}
Response: 200 OK{ "status": "saved" }| Field | Type | Description |
|---|---|---|
maxCostUsdPerDay |
number | Max USD spend across all runs in one budget day. Blocks once the day’s recorded spend exceeds it |
maxCostUsdPerRun |
number | Max USD for one run. Enforced mid-run for workflow runs only (see what is enforced where). Elsewhere it is checked only by the opt-in POST /v1/runs/forecast and reported after the fact as an anomaly_detected event |
maxTokensPerDay |
integer | Max total tokens (in + out) per day. Blocks once the day’s recorded tokens reach it |
maxRunsPerDay |
integer | Max runs per day. Blocks once the day’s run count reaches it. Spend inside a run (workflow ai-steps, votes, tools) does not add to the count. A workflow run counts once, when it succeeds, like a plain run. Failed runs are not counted |
toolLimits |
object | Per-tool call-count limits per day. Keys are a tool name (web_search) or connector.action for connector nodes. Enforced for workflow tool and connector nodes only |
hardFail |
boolean | true: a reached limit blocks the call. false: the breach is logged and the call proceeds |
notifyAtPct |
integer | Stored; defaults to 80 when omitted or outside 1-100. No alert is sent on it today |
Day boundary. The daily rollup resets at local midnight using LANTERN_DEFAULT_TIMEZONE (deployment-wide IANA zone; defaults to UTC when unset). A schedule’s own timezone affects only when its cron fires, not the budget day.
What is enforced where
Section titled “What is enforced where”Each check runs before the model or tool call. “Yes” means a hard-fail budget blocks; a soft budget logs and proceeds. Tenant cap is the tenant-wide daily cost cap (below). Columns are in this order: cost/day, tokens/day, runs/day, tenant cap, per-run cap, per-tool.
- Run create (
POST /v1/runs), session message,/v1/completionswithagentName: Yes, Yes, Yes, Yes, No, No. /v1/completionswithoutagentName: only the tenant cap (Yes); the rest n/a.- Workflow
ai-step(and confidence votes): cost Yes (every call), tokens Yes (every call), runs/day No (run already admitted), tenant Yes (every call), per-run Yes (against spend accrued so far), per-tool n/a. - Workflow
toolnode,web_search: cost Yes, tokens Yes, runs/day No (run already admitted), tenant Yes, per-run Yes (against spend accrued so far), per-tool Yes. - Workflow
toolnode, sandbox tools: only per-tool (Yes); everything else No. - Workflow
connectornode: only per-tool (Yes, keyedconnector.action); everything else No. web_searchinside a session turn: covered by the session-message check at the start of the turn; its spend is recorded after.- Voice (Twilio inbound, LiveKit token): cost Yes, tokens Yes, runs/day Yes, tenant Yes, per-run flat estimate only, per-tool No.
Marketplace invokes check the seller agent’s budget and return 402 with seller agent budget limit reached: <reason>.
What a blocked call looks like
Section titled “What a blocked call looks like”POST /v1/runs, hard-fail budget reached. The reason text names the limit that tripped:
HTTP 402{ "error": "agent budget limit reached: daily run limit reached (100/100)", "reason": "daily run limit reached (100/100)"}Other reason strings:
daily spend would reach $5.0123 exceeding limit $5.0000daily token limit reached (500000/500000)tenant-wide daily spend would reach $50.0100 exceeding tenant limit $50.0000run spend $1.0042 reached per-run limit $1.0000tool "web_search" budget exhausted (50/50 today)
POST /v1/completions (agent-scoped or agentless) uses a shorter body:
HTTP 402{ "error": "budget limit exceeded", "reason": "<reason>" }Session messages have no HTTP error: the session replies with sorry — this agent has reached its usage limit for today and goes idle. Workflow steps fail with budget limit exceeded: <reason>. Voice returns Twilio <Reject reason="busy"/> or, for other providers, 402 agent voice budget exhausted; the LiveKit token route returns 402 { "error": "agent voice budget exhausted: <reason>" }.
When the budget cannot be read
Section titled “When the budget cannot be read”A database error while reading a budget is not the same as “no budget configured” (that allows the call). The check fails closed when the budget is hard-fail, or when the row itself could not be read (its policy is unknown, so it is treated as hard-fail). The error text is logged, never returned.
POST /v1/runs -> HTTP 503{ "error": "budget check unavailable; retry shortly", "reason": "budget check unavailable"}- 503 is returned by run create only.
/v1/completionsanswers 402 with reasonbudget check unavailable; voice declines as for a budget block (Twilio<Reject>, other providers a plain-text 402, the LiveKit token route 402agent voice budget exhausted: budget check unavailable); sessions replysorry — I can't check this agent's usage limit right now, try again shortly; workflow steps fail withbudget limit exceeded: budget check unavailable. - Soft budgets: if the budget row was read (and says
hardFail: false) but the usage lookup then errors, the call proceeds. If the row itself cannot be read, the call is blocked whatever the policy. - Every failed-closed lookup increments
lantern.budget.check.errors(see metrics).
Per-run cap inside a workflow
Section titled “Per-run cap inside a workflow”Workflow runs record each model call’s tokens and cost onto the run as they happen. Before every ai-step, every self-consistency confidence vote and every web_search tool node, the interpreter re-checks: tenant cap, the agent’s daily cost and token caps, and maxCostUsdPerRun against what this run has spent so far. Hard-fail stops the run at that step with no further provider spend; maxRunsPerDay is skipped so other runs finishing do not stop a run that was already admitted.
Per-tool limits in workflows
Section titled “Per-tool limits in workflows”toolLimits is checked before a workflow tool or connector node dispatches, and one use is counted after dispatch. Hard-fail blocks the step; soft logs and proceeds. A tool that was never dispatched (runtime not wired) is not counted. See workflow tool nodes.
Tenant-wide cap
Section titled “Tenant-wide cap”One daily cap across all agents, including agentless /v1/completions calls: PUT, GET and DELETE on /v1/budgets/tenant with { "maxCostUsdPerDay": 50, "hardFail": true } (must be greater than 0). It is stored under the reserved agent name *, hidden from GET /v1/budgets, and the per-agent routes reject * as a name. A soft tenant cap never masks an agent’s own hard-fail limit.
Reading and removing
Section titled “Reading and removing”GET /v1/agents/{name}/budgetResponse: 200 OK{ "agentName": "research-agent", "maxCostUsdPerDay": 5.00, "hardFail": true, ... }404 {"error":"no budget configured"} when none is set
GET /v1/budgetsResponse: 200 OK, bare array of per-agent budgets
DELETE /v1/agents/{name}/budgetResponse: 200 OK{ "status": "removed" }Try it
Section titled “Try it”TOKEN=$(curl -s localhost:8080/auth/login -H 'Content-Type: application/json' \ -d '{"email":"admin@lantern.dev","password":"lantern"}' | jq -r .token)
# Cap an agent at 1 run per day, hard-failcurl -s -X PUT localhost:8080/v1/agents/demo/budget \ -H "Authorization: Bearer $TOKEN" -H 'Content-Type: application/json' \ -d '{"maxRunsPerDay":1,"hardFail":true}'
# Create two runs; the second returns HTTP 402 once the first is recordedcurl -s -i -X POST localhost:8080/v1/runs \ -H "Authorization: Bearer $TOKEN" -H 'Content-Type: application/json' \ -d '{"agentName":"demo","input":{"q":"hi"}}'Usage is recorded when a run finishes, so create the second run after the first completes.
Pre-run cost forecast
Section titled “Pre-run cost forecast”POST /v1/runs/forecast estimates tokens and cost from the agent’s succeeded runs over the last 30 days (average tokens per run, plus about one token per four characters of input) and checks the estimate against the agent’s budget. It answers 402 instead of 200 when a hard-fail budget would be breached. Forecasting is opt-in: run creation does not call it.
- With history the response is
calibrated: trueand the per-run cap and daily cost cap are checked against the estimate. - With no succeeded runs the estimates are omitted,
calibratedis false,confidenceis 0, and onlymaxRunsPerDaycan block. An unknown cost never auto-blocks. confidencegrows with sample size:min(0.95, 0.3 + 0.03 × √runs).
POST /v1/runs/forecastContent-Type: application/json
{ "agentName": "research-agent", "input": "quantum computing" }
Response: 200 OK   (values illustrative){  "agentName": "research-agent",  "model": "...",  "provider": "...",  "estimatedTokensIn": 800,  "estimatedTokensOut": 2000,  "estimatedCostUsd": 0.004,  "confidence": 0.45,  "calibrated": true,  "reasoning": { "historical_runs": 25, "input_token_estimate": 5, ... },  "budget": { "maxCostUsdPerRun": 1, "spentTodayUsd": 0.12, "runsToday": 4,              "maxRunsPerDay": 100, "hardFail": true, ... },  "wouldExceedBudget": false}
// Over budget (HTTP 402 when hardFail is true). Several reasons join with "; ":{  ...,  "estimatedCostUsd": 1.2,  "wouldExceedBudget": true,  "blockReason": "per-run cost $1.2000 exceeds limit $1.0000"}
Other blockReason strings: daily cost would hit $5.0400 exceeding $5.0000, daily run limit reached (100/100). blockReason is omitted when nothing would block.
Voice calls
Section titled “Voice calls”Voice calls count against the same agent_budgets as runs. An inbound call over a hard-fail budget is declined before any media is allocated (Twilio: <Reject reason="busy"/>; LiveKit: HTTP 402 on the token request). A flat cost estimate is reserved on connect, then reconciled to the actual call duration when the provider status callback fires at POST /v1/voice/calls/status/{provider}.
Not enforced yet
Section titled “Not enforced yet”- Per-run cap mid-run on single-call paths. A plain (non-workflow) run, a session turn and a completion make one model call, so there is no point to stop at.
maxCostUsdPerRunis not checked at run create (the estimate there is 0). Overshoot is reported after the run as ananomaly_detectedjournal event, which does not block anything. - Pre-run cost estimates at run creation. Run create checks recorded spend, not projected spend, so the run that crosses a daily cap is allowed; the next one is blocked. Use
POST /v1/runs/forecastto estimate ahead of time. - Failed runs toward runs/day. Only runs that succeed are counted toward
maxRunsPerDay(a workflow run counts once on success), so an agent that keeps failing never trips the cap. Its spend still counts toward the cost and token caps. - Per-tool limits outside workflows. Session tool loops,
POST /v1/connectors/{id}/executeand other callers do not consulttoolLimits. - Daily cost and token caps on sandbox tool and connector nodes. Those nodes check only
toolLimits; their ai-step neighbours carry the model spend and are checked. - No reservation. Checks read recorded usage and spend is recorded after the call, so concurrent calls can together overshoot a cap.
notifyAtPctalerts. The value is stored; nothing fires on it yet.
Metrics
Section titled “Metrics”| Metric | Attributes | Meaning |
|---|---|---|
lantern.run.budget.blocks |
lantern.agent_name |
Runs refused by a hard-fail budget at POST /v1/runs (HTTP 402) |
lantern.budget.check.errors |
lantern.budget_check (tenant, agent, run, tool), lantern.agent_name |
Budget lookups that errored and failed closed |